

What actually happens?
Traditional backups copy entire files or virtual disks, which takes time and slows down your system. Nutanix uses a Redirect-on-Write (RoW) architecture combined with instantaneous metadata pointers.
1️⃣ 𝘛𝘩𝘦 𝘗𝘰𝘪𝘯𝘵𝘦𝘳𝘴 𝘍𝘳𝘦𝘦𝘻𝘪𝘯𝘨 (𝘐𝘯𝘴𝘵𝘢𝘯𝘵):
- Instead of copying your data blocks, Nutanix copies the metadata map (the index or map that tells the system where your data blocks live on the physical disks).
* The Process: The system takes a snapshot of this map, which takes milliseconds because metadata is incredibly small.
* The Result: The original data blocks become read-only for that specific point in time.
2️⃣ 𝘛𝘩𝘦 𝘙𝘦𝘥𝘪𝘳𝘦𝘤𝘵-𝘰𝘯-𝘞𝘳𝘪𝘵𝘦 𝘔𝘦𝘤𝘩𝘢𝘯𝘪𝘴𝘮 (𝘕𝘰 𝘖𝘷𝘦𝘳𝘩𝘦𝘢𝘥):
- The moment after the recovery point is created, your Virtual Machine (VM) keeps running and writing new data.
* Old Data: Stays exactly where it was, safely frozen as your recovery point.
* New Data: Instead of overwriting old data, any new changes are written to completely new locations on the storage array. The VMs active metadata map is updated to point to these new locations.
* Because no data was moved or copied during the creation phase, there is zero impact on VM performance and no waiting time.
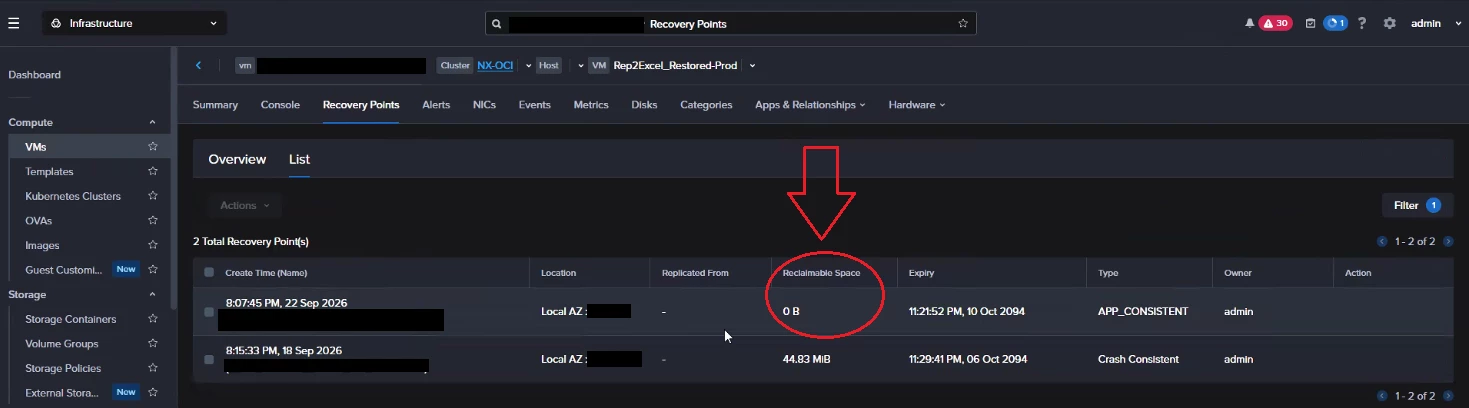
3️⃣ 𝘞𝘩𝘺 𝘙𝘦𝘤𝘭𝘢𝘪𝘮𝘢𝘣𝘭𝘦 𝘚𝘱𝘢𝘤𝘦 𝘚𝘩𝘰𝘸𝘴 0 𝘉:
- The Reclaimable Space column displays the unique data blocks that would be physically deleted and freed up from the storage pool if only that specific snapshot were deleted.
- Because Nutanix snapshots use a Redirect-on-Write (RoW) and pointers architecture, consecutive recovery points share overlapping blocks. If the data inside the VM hasnt changed much between snapshots, or if those blocks are still referenced by other active recovery points in the chain, deleting just this snapshot yields 0 bytes of extra capacity back to the cluster
𝗧𝗵𝗮𝘁 𝗺𝗮𝗸𝗲𝘀 𝘁𝗵𝗲 𝗶𝗻𝗶𝘁𝗶𝗮𝗹 𝘀𝗻𝗮𝗽𝘀𝗵𝗼𝘁 𝗼𝗽𝗲𝗿𝗮𝘁𝗶𝗼𝗻 𝗲𝘅𝘁𝗿𝗲𝗺𝗲𝗹𝘆 𝗳𝗮𝘀𝘁, 𝗿𝗲𝗴𝗮𝗿𝗱𝗹𝗲𝘀𝘀 𝗼𝗳 𝘄𝗵𝗲𝘁𝗵𝗲𝗿 𝘁𝗵𝗲 𝗩𝗠 𝗶𝘀 𝟱𝟬 𝗚𝗕, 𝟱𝟬𝟬 𝗚𝗕, 𝗼𝗿 𝘀𝗲𝘃𝗲𝗿𝗮𝗹 𝗧𝗕.